
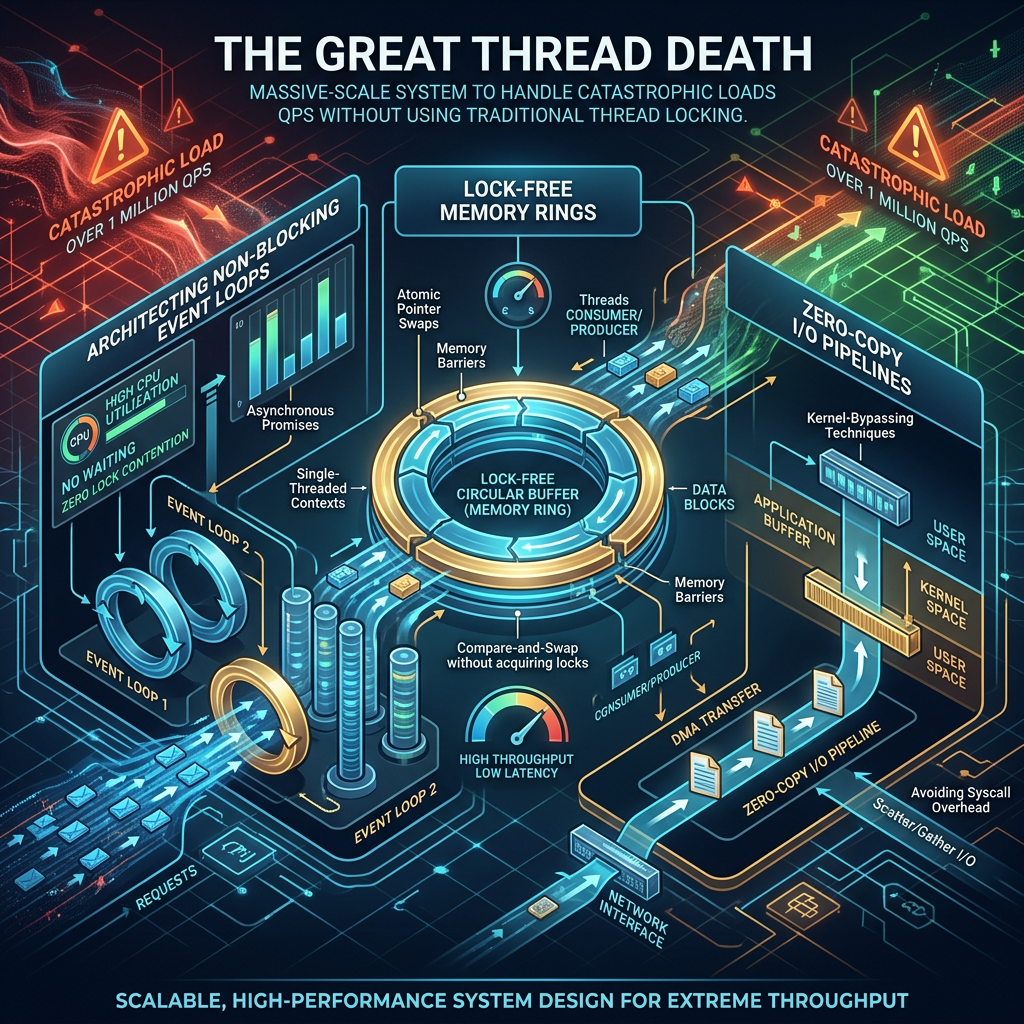
The Anatomy of Server-Side Breakdown
Every backend engineering career hits a defining moment when an application that performed flawlessly in staging suddenly collapses in production. The metrics dashboards flicker yellow, then red: HTTP 504 Gateway Timeouts surge, database connection pools deplete in seconds, garbage collection pauses spike from milliseconds to multi-second freezes, and p99 latency degrades by three orders of magnitude.
When early-career engineers inspect these meltdowns, their instinct is often to point to insufficient hardware or application-level bugs: “The server ran out of CPU,” or “The database query was missing an index.”
However, at scale—specifically when driving systems toward 1,000,000 Queries Per Second (QPS) on modern high-density hardware—the failure mode is rarely a lack of raw compute capacity. Instead, it is systemic protocol congestion and OS-kernel thrashing, a phenomenon we refer to as The Great Thread Death.
                           +------------------------------------+
                           |    1,000,000 QPS Ingress Traffic   |
                           +------------------------------------+
                                             |
                                             v
                           +------------------------------------+
                           |    Operating System Kernel Network |
                           |       Socket Buffer (TCP/eBPF)     |
                           +------------------------------------+
                                             |
                   +-------------------------+-------------------------+
                   |                                                   |
                   v                                                   v
     [ TRADITIONAL BLOCKED MODEL ]                     [ NON-BLOCKING EVENT LOOP MODEL ]
   +-------------------------------+                 +-------------------------------+
   | Thread 1  -> Blocked on DB    |                 | Event Loop Engine (epoll/kqueue) |
   | Thread 2  -> Context Switch   |                 | Single Thread per Core (100% CPU)|
   | Thread 3  -> Mutex Lock Wait  |                 | Lock-Free Ring Buffers (CAS)  |
   | Thread N  -> Cache Trashing   |                 | Zero-Copy User Memory Buffer  |
   +-------------------------------+                 +-------------------------------+
                   |                                                   |
                   v                                                   v
     [ SYSTEM COLLAPSE / FAIL ]                        [ SUB-MILLISECOND CONTINUOUS FLUID ]
   - Tail Latency: 15,000 ms                         - Tail Latency: 1.2 ms
   - CPU Overhead: 85% Kernel Context Sw             - CPU Overhead: 98% User Compute
   - Memory: Out-Of-Memory OOM Killer                - Memory: Flat Pre-Allocated Ring
The Invisible Execution Bottlenecks
When high-throughput server architectures fail, they exhibit four underlying physical bottlenecks:
- Context-Switching Thrashing: Operating system kernel schedulers consuming 80%+ of total CPU cycles swapping thread execution contexts, CPU registers, and pointer registers, leaving less than 20% of compute budget for actual application code execution.
- L1/L2/L3 CPU Cache Invalidation: Thread hopping across hardware CPU cores, causing constant cache-line invalidation and forcing execution pipelines to stall for hundreds of cycles while fetching data from remote main memory (DRAM/NUMA nodes).
- Mutex Contention and Lock Convoy Effects: Thread queues backing up behind synchronized locks, turning parallel execution pipelines into serialized, single-threaded bottlenecks.
- Kernel-to-User Space Memory Copy Overhead: Continuous deep-copying of network payload buffers across the OS kernel boundary into application heap memory, saturating memory bus bandwidth and triggering catastrophic runtime Garbage Collection (GC) pauses.
To build resilient, high-throughput backend services, engineers must understand how hardware registers, CPU cache lines, OS kernel schedulers, memory buses, and async runtimes interact. This blog breaks down these low-level interactions step-by-step.
2. The Mechanics of Execution: Context Switching, Cache Line Trashing, and Mutex Contention
The Thread-per-Request Anti-Pattern
To understand why traditional backend architectures break down, let’s examine the classical Thread-per-Request model (historically utilized by early Tomcat, Apache HTTP, and baseline enterprise Java application servers).
   Incoming HTTP Request
            │
            ▼
   ┌──────────────────┐
   │ Accept Connection│
   └────────┬─────────┘
            │
            ▼
   ┌────────────────────────────────────────────────────────┐
   │ Spawn / Assign OS Thread from Pool (e.g., Thread #412)│
   └────────┬───────────────────────────────────────────────┘
            │
            ├───► Read Socket Input Stream (Blocking I/O)
            │
            ├───► Execute Business Logic
            │
            ├───► Query Database over TCP (Blocking I/O)
            │
            ├───► Write Socket Response Stream (Blocking I/O)
            │
            ▼
   ┌────────────────────────────────────────────────────────┐
   │ Return Thread #412 back to Pool                        │
   └────────────────────────────────────────────────────────┘
When 50,000 concurrent HTTP requests hit this architecture simultaneously, the runtime attempts to maintain 50,000 active threads (or queue them across fixed thread pools of thousands of instances).
What happens at the CPU & OS Kernel layer?
- Memory Allocation Footprint: Every native OS thread allocated by a runtime (such as the JVM or Linux pthreads) demands its own execution stack space (typically 1 MB per thread by default). Allocating 50,000 threads consumes 50 GB of RAM purely on stack frame memory overhead before storing a single byte of business logic domain model.
- Kernel Task Struct Allocation: The Linux kernel must create a
task_structentry for every thread, overwhelming the Completely Fair Scheduler (CFS). - The Cost of Preemption: When the OS kernel pauses Thread A to execute Thread B, it must execute a context switch:
- Flush CPU registers (Accumulator, Index, Stack Pointer, Instruction Pointer).
- Save floating-point registers and execution state into the Kernel Task State Segment.
- Switch translation lookaside buffers (TLB) and page tables if switching execution context boundaries.
- Reload hardware registers with Thread B’s saved state.
Hardware Execution Cost of a Native Thread Context Switch:----------------------------------------------------------------------Register Save/Restore Overhead : ~1,000 - 3,000 CPU CyclesTLB Flush / Address Space Swaps : ~2,000 - 5,000 CPU CyclesL1/L2 Cache Invalidation Penalty : ~10,000 - 30,000 CPU Cycles----------------------------------------------------------------------Total Penalty Per Context Switch : Up to 38,000 CPU Cycles Lost!At 50,000 threads thrashing 100x/sec : 190,000,000,000 CPU Cycles WASTED/sec!
CPU Cache Hierarchy & Memory Bus Bottlenecks
Modern server architecture relies on an explicit memory hierarchy designed to bridge the massive speed gap between CPU clock cycles (~0.2 nanoseconds) and main memory access (~100 nanoseconds).
+-------------------------------------------------------------------+| CPU CORE || +-------------------------------------------------------------+ || | Execution Engine (ALU / Vector Registers) | || +-------------------------------------------------------------+ || | L1 Data Cache (32 KB - 64 KB) | Latency: ~0.5 - 1.0 ns | || +-------------------------------------------------------------+ || | L2 Cache (512 KB - 1 MB) | Latency: ~3.0 - 4.0 ns | |+--+---------------------------------+---------------------------+--+ | L3 Cache (Shared across Cores) (32MB-256MB) | Latency: ~10-15 ns| +---------------------------------------------+-------------------+ | Main Memory DRAM (Up to Terabytes) | Latency: ~60-100 ns| +---------------------------------------------+-------------------+
The Hardware Reality of False Sharing
When multiple threads execute on different CPU cores and modify adjacent data variables residing inside the same 64-byte Cache Line, the CPU hardware architecture invokes the MESI (Modified, Exclusive, Shared, Invalid) cache-coherency protocol over the interconnect bus.
Core 1 Cache (L1) Core 2 Cache (L1)+-------------------------------+ +-------------------------------+| Cache Line (64 Bytes) | | Cache Line (64 Bytes) || [Var A (8B) | Var B (8B)] | | [Var A (8B) | Var B (8B)] || Status: MODIFIED | | Status: INVALIDATED |+-------------------------------+ +-------------------------------+ │ ▲ │ Hardware Interconnect (Bus Lock) │ └──────────────────────────────────────┘
- Core 1 updates
Var A. Core 1’s cache line status flips to MODIFIED. - Core 2’s L1 cache line containing
Var Bis immediately INVALIDATED by hardware interconnect signals, even though Core 2 never accessedVar A! - Core 2 attempts to read
Var B. It experiences a cache miss, stalls execution, and forces a fetch directly across the memory interconnect from Core 1’s L1 cache or main DRAM.
This issue, known as False Sharing, causes parallel code running on a 64-core enterprise server to execute slower than single-threaded code due to continuous cache line thrashing.
Mutex Contention Mechanics & The Convoy Effect
When multiple concurrent threads contend for a standard mutual exclusion lock (std::mutex in C++, ReentrantLock in Java, or pthread_mutex_t in C), the OS kernel handles contention through a system call sleep mechanism (e.g., Linux futex).
Thread 1 (Holds Mutex) --------[ Processing Business Logic ]--------> Release Mutex │Thread 2 (Wants Mutex) --[ Tries Lock ]--> Blocked (Enters Futex Wait) ─────┤ (Woken by OS Kernel) │Thread 3 (Wants Mutex) --[ Tries Lock ]--> Blocked (Enters Futex Wait) ─────┤ (Enters Lock Queue) │Thread 4 (Wants Mutex) --[ Tries Lock ]--> Blocked (Enters Futex Wait) ─────┘
The Cascade of Degradation:
- Thread 1 acquires the lock and enters a critical section.
- Thread 2 attempts to acquire the lock, fails, and executes a context-switch into kernel mode to sleep via
futex(FUTEX_WAIT). - Threads 3, 4, and 5 arrive, fail, and sleep, building a long Lock Convoy Queue.
- When Thread 1 releases the lock, the kernel must execute a
futex(FUTEX_WAKE)call, context-switch Thread 2 back into execution context, re-validate cache lines, and check for execution status. - By the time Thread 2 wakes up (10 to 50 microseconds later), CPU resources have sat idle during the wake-up transition while thousands of incoming network requests continue to pile up in the OS socket buffer.
3. Demystifying Non-Blocking I/O: Kernel Epoll, Reactive Runtimes, and Event Loops
To break free from thread exhaustion, high-performance server architectures switch from thread-per-request models to Non-Blocking, Event-Driven Architecture.

The fundamental primitive enabling this transformation is the OS-level I/O Multiplexing mechanism:
epollon Linux,kqueueon BSD/macOS, andIOCPon Windows.
Deep-Dive: How Linux epoll Works Under the Hood
Instead of assigning a thread to wait on a network socket, the application registers thousands of network file descriptors (FDs) with a single kernel epoll instance.
                           +-------------------------------------+
                           | User-Space Event Loop Engine        |
                           +-------------------------------------+
                                     |             ▲
              1. epoll_wait() System |             | 4. Returns Ready
                 Call (Non-Blocking) |             |    File Descriptors
                                     v             |
                           +-------------------------------------+
                           | Operating System Linux Kernel       |
                           |                                     |
                           |   +-----------------------------+   |
                           |   | Red-Black Tree (O(log N))   |   |
                           |   | Holds registered Socket FDs |   |
                           |   +-----------------------------+   |
                           |                 │                   |
                           |                 ▼                   |
                           |   +-----------------------------+   |
                           |   | Ready Interest Doubly-Linked|   |
                           |   | List (O(1) Access)          |   |
                           |   +-----------------------------+   |
                           +-------------------------------------+
                                     ▲
                                     | 3. Hardware Interrupt
                                     |    Populates Ready List
                           +-------------------------------------+
                           | Network Interface Card (NIC / DMA)  |
                           +-------------------------------------+
The Internal Kernel Data Structures of epoll:
- The Red-Black Tree (
epitementries): When you register a file descriptor usingepoll_ctl(epfd, EPOLL_CTL_ADD, fd, &event), the kernel inserts the FD into a balanced Red-Black Tree in kernel memory. This allows $O(\log N)$ registration, modification, and deletion of monitored sockets across millions of open connections. - The Ready List (Doubly-Linked List): When network packets arrive at the Network Interface Card (NIC), hardware Direct Memory Access (DMA) writes the payload to RAM and triggers an interrupt handler. The kernel’s socket callback places any FD that received data directly into
epoll‘s Ready Doubly-Linked List. - The
epoll_wait()System Call: The user-space event loop thread callsepoll_wait(). The kernel checks the Ready List. If the list is populated, it copies only the ready event notifications into user memory in $O(1)$ time complexity—regardless of whether you are monitoring 10 sockets or 1,000,000 sockets!
Comparing Non-Blocking Mechanisms
| Primitive | OS Platform | Scalability Complexity | Kernel Data Structure | Performance Profile at Scale |
select() | POSIX / Universal | $O(N)$ Linear Scan | Fixed Bit Array (1024 limit) | Terrible. Re-scans all sockets every call. |
poll() | POSIX / Universal | $O(N)$ Linear Scan | Array of pollfd structs | Poor. Unbounded FDs, but still scans entire array. |
epoll | Linux Kernel | $O(1)$ Event Return | Red-Black Tree + Ready List | Outstanding. Scalable to millions of concurrent sockets. |
kqueue | BSD / macOS | $O(1)$ Event Return | Array / Hash Table + Filter List | Outstanding. Highly optimized BSD kernel primitive. |
io_uring | Modern Linux (5.1+) | $O(1)$ Zero-Syscall Ring | Kernel-User Shared Ring Buffer | Absolute Peak. Fully asynchronous, zero syscall overhead. |
Event Loop Starvation & CPU-Bound Blocking Operations
While an event loop engine (such as Node.js Libuv, Netty EventLoop Group, Tokio Runtime in Rust, or Vert.x) handles I/O efficiently, it introduces a major failure mode: Event Loop Starvation.
Single-Threaded Event Loop Engine:[ Read Socket ] -> [ Parse JSON ] -> [ Sync CPU Intensive Task ] -> [ Write Socket ] ▲ │ DANGER ZONE! │ Event Loop Stalls Here for 500ms │ 50,000 Ingress Requests Dropped!
If a developer executes a single synchronous, CPU-heavy operation on the event loop thread—such as synchronous JSON parsing of a 50MB payload, cryptographic hashing, or a blocking file read—the entire server halts.
Preventing Event Loop Starvation:
                          +-----------------------------------+
                          |  Ingress Event Loop Engine        |
                          |  (Handles epoll socket I/O only)  |
                          +-----------------------------------+
                                            |
                         Is task CPU heavy or Blocking Disk I/O?
                                            |
                           +----------------+----------------+
                           | Yes                             | No
                           v                                 v
            +------------------------------+  +------------------------------+
            | Dispatch to Dedicated Worker |  | Execute Non-Blocking Async   |
            | Worker Thread Pool / Channel |  | Task Directly on Event Loop  |
            +------------------------------+  +------------------------------+
To preserve sub-millisecond execution times, never execute synchronous blocking code inside an Event Loop thread. Offload CPU-heavy operations and blocking disk operations to dedicated Worker Thread Pools using non-blocking channels.
4. Architecting High-Throughput Memory Structures: Lock-Free Ring Buffers & CAS Primitives
When building high-throughput systems that pass millions of messages per second between event loop threads and worker thread pools, traditional synchronized blocking queues (java.util.concurrent.LinkedBlockingQueue or C++ std::mutex protected queues) become major performance bottlenecks.
To eliminate thread contention and lock overhead, elite systems use Lock-Free Ring Buffers (pioneered by LMAX Disruptor architecture).

Atomic Operations & Compare-And-Swap (CAS) Mechanics
Lock-free architectures replace kernel-level mutex locks with hardware-level Compare-And-Swap (CAS) atomic primitives.
At the assembly layer, modern x86 CPU architectures supply instructions like LOCK CMPXCHG (Compare and Exchange).
                    CMPXCHG Memory Address, Expected Value, New Value
                                           │
          ┌────────────────────────────────┴────────────────────────────────┐
          ▼                                                                 ▼
[ Value in Memory == Expected Value ]                            [ Value in Memory != Expected Value ]
  • Update Memory to New Value                                     • Do NOT Update Memory
  • Set CPU Zero Flag (ZF = 1)                                     • Load Actual Memory Value into Register
  • SUCCESS                                                        • Set CPU Zero Flag (ZF = 0)
                                                                   • FAIL (Retry Loop)
Production Lock-Free Ring Buffer Implementation (Rust)
Below is a production-grade lock-free Single-Producer Single-Consumer (SPSC) Ring Buffer written in Rust, leveraging atomic memory ordering semantics (Acquire / Release) to ensure hardware-level synchronization without locks:
Rust
use std::sync::atomic::{AtomicUsize, Ordering};use std::sync::Arc;use std::cell::UnsafeCell;/// A high-performance, fixed-capacity, lock-free SPSC Ring Buffer./// Designed for sub-microsecond IPC message passing between server threads.pub struct LockFreeRingBuffer<T, const CAP: usize> { buffer: [UnsafeCell<Option<T>>; CAP], head: AtomicUsize, // Written by Producer, Read by Consumer tail: AtomicUsize, // Written by Consumer, Read by Producer}// Safety: LockFreeRingBuffer is thread-safe for SPSC pattern.unsafe impl<T: Send, const CAP: usize> Sync for LockFreeRingBuffer<T, CAP> {}unsafe impl<T: Send, const CAP: usize> Send for LockFreeRingBuffer<T, CAP> {}impl<T, const CAP: usize> LockFreeRingBuffer<T, CAP> { pub fn new() -> Self { assert!(CAP.is_power_of_two(), "Capacity MUST be a power of two for fast bitwise masking!"); Self { buffer: std::array::from_fn(|_| UnsafeCell::new(None)), head: AtomicUsize::new(0), tail: AtomicUsize::new(0), } } /// Enqueues an item into the ring buffer without locking. /// Returns Err(item) if the ring buffer is completely full. pub fn push(&self, value: T) -> Result<(), T> { let current_head = self.head.load(Ordering::Relaxed); let current_tail = self.tail.load(Ordering::Acquire); // Check if the ring buffer is full if current_head.wrapping_sub(current_tail) >= CAP { return Err(value); // Ring Buffer Full - Apply Backpressure! } // Fast bitwise wrap-around using capacity power-of-two mask (CAP - 1) let index = current_head & (CAP - 1); unsafe { let slot = self.buffer[index].get(); *slot = Some(value); } // Release ordering guarantees memory writes complete before updating head atomic index self.head.store(current_head.wrapping_add(1), Ordering::Release); Ok(()) } /// Dequeues an item from the ring buffer without locking. /// Returns None if the ring buffer is currently empty. pub fn pop(&self) -> Option<T> { let current_tail = self.tail.load(Ordering::Relaxed); let current_head = self.head.load(Ordering::Acquire); // Check if the ring buffer is empty if current_tail == current_head { return None; // Buffer Empty } let index = current_tail & (CAP - 1); let value = unsafe { let slot = self.buffer[index].get(); (*slot).take() }; // Release ordering guarantees consumer reading completes before updating tail atomic index self.tail.store(current_tail.wrapping_add(1), Ordering::Release); value }}
Eliminating Cache Line False Sharing with Memory Padding
Notice how head and tail in high-throughput lock-free queues reside right next to each other in memory structure definitions. If CPU Core 1 constantly writes to head while CPU Core 2 constantly writes to tail, the two cores will trigger False Sharing cache-line invalidation cycles on every write operation.
To fix this issue, cache line padding must be inserted to guarantee that the producer pointer and consumer pointer reside on completely independent 64-byte hardware cache lines:
Rust
#[repr(align(64))] // Align struct explicit to 64-byte boundarystruct PaddedAtomicUsize { value: AtomicUsize, _padding: [u8; 56], // 8 bytes value + 56 bytes padding = 64 bytes (1 Cache Line)}
5. Zero-Copy Networks: Eliminating Kernel-to-User Space Overhead (io_uring, eBPF, DMA)
In traditional HTTP/gRPC server applications, processing a single ingress packet involves multiple copy operations across execution context boundaries:
+-----------------------------------------------------------------------------------+| TRADITIONAL DATA PATH (4 COPIES, 4 CONTEXT SWITCHES PER REQUEST) || || NIC Hardware --> [ DMA Copy ] --> Kernel Ring Buffer (sk_buff) || │ || ▼ [ Copy #2: Syscall read() ] || User Space Heap Memory Buffer || │ || ▼ [ Application Processing / Mutation ] || Modified User Application Buffer || │ || ▼ [ Copy #3: Syscall write() ] || Kernel Socket Output Buffer || │ || NIC Network Wire <--- [ DMA Copy #4 ] ─┘ |+-----------------------------------------------------------------------------------+
The Cost of Data Copying at Scale
At 1,000,000 QPS with an average request payload size of 64 KB:
$$\text{Data Transfer Rate} = 1,000,000 \times 64\,\text{KB} = 64\,\text{GB/sec}$$
If the operating system copies this memory 4 times across kernel boundaries, total memory bus traffic reaches 256 GB/sec! This volume saturates RAM memory bus bandwidth, spikes CPU usage, and lowers throughput.
The Modern Zero-Copy Pipeline
Modern high-performance server architectures use zero-copy mechanisms to stream data directly across network interfaces and application buffers without intermediate copying.
+-----------------------------------------------------------------------------------+| ZERO-COPY Modern Data Path (io_uring / eBPF / Kernel-Bypass) || || NIC Hardware --> [ Direct DMA Copy ] --> Pre-Allocated Shared Ring Buffer || (Shared between Kernel and User-Space) || │ || ▼ || Zero Context Switch Engine (Zero Copy Operations!) || │ || NIC Network Wire <---------- [ Direct DMA Outbound ]─────────────────────────────┘+-----------------------------------------------------------------------------------+
Deep Dive: Linux io_uring Zero-Syscall Asynchronous I/O
Introduced in Linux Kernel 5.1, io_uring provides high-throughput asynchronous system call execution using two lock-free ring buffers shared directly between kernel memory and user application space.
+-------------------------------------------------------------------+| USER APPLICATION SPACE || || +--------------------------+ +--------------------------+ || | Submission Queue (SQ) | | Completion Queue (CQ) | || | User writes I/O Requests | | User reads Completed Result| || +-------------┬------------+ +─────────────▲------------+ |+─────────────────┼─────────────────────────────────┼───────────────+| │ Shared Memory Ring Buffers │ || │ (Zero Copy / Zero Syscall) | |+─────────────────┼─────────────────────────────────┼───────────────+| ▼ │ || +--------------------------+ +─────────────┴────────────+ || | Kernel Submission Handler| | Kernel Completion Ring | || +--------------------------+ +--------------------------+ || || LINUX KERNEL SPACE |+-------------------------------------------------------------------+
- Submission Queue (SQ): The user application prepares read/write requests and writes them to the SQ ring buffer in user memory.
- Completion Queue (CQ): When the kernel completes the I/O request via background kernel threads or hardware interrupts, it appends the results directly to the CQ ring buffer.
- Kernel Polling Mode (
IORING_SETUP_SQPOLL): The kernel runs a background kernel thread polling the Submission Queue. The user application can issue thousands of network reads and writes without executing a singlesyscallcontext switch!
6. The Distributed Edge: Preventing Cache Stampedes and the Thundering Herd Problem
Even when an individual backend server node is tuned for non-blocking I/O and zero-copy memory pipelines, system-wide failure can still occur at the distributed infrastructure layer due to Thundering Herd problems and Cache Stampedes.

The Mechanics of a Cache Stampede Collapse
Consider a high-traffic e-commerce microservice handling 500,000 QPS. The service reads popular product information directly from an in-memory Redis cluster cache.
       500,000 Incoming QPS
                 │
                 ▼
     +───────────────────────+
     | In-Memory Cache Engine|  <--- Key Expires! (TTL = 0)
     +───────────────────────+
                 │
                 │ 500,000 Cache Misses Simultaneously!
                 ▼
     +───────────────────────+
     | PostgreSQL Database   |  <--- CATASTROPHIC COLLAPSE!
     +───────────────────────+       (Connections Exceeded, OOM Killer)
- The cached object key
product:hot_item_101reaches its Time-To-Live (TTL) expiration and drops from the cache. - In the next 10 milliseconds, 5,000 concurrent event loop threads query Redis, receive a
CACHE_MISS, and fall back to querying the primary PostgreSQL database. - The primary database receives 5,000 intensive SQL queries simultaneously, depleting its connection pool, driving CPU utilization to 100%, and spiking latency from 2 ms to 15,000 ms.
- Subsequent web requests time out, causing clients to auto-retry and triggering a Distributed Cascading Failure.
Solution 1: Probabilistic Early Expiration (XFetch Algorithm)
Instead of relying on hard TTL expiration, elite backend systems implement the XFetch Probabilistic Early Expiration Algorithm (Vattani et al.).
Python
import mathimport randomimport timedef get_with_xfetch(redis_client, db_client, key, beta=1.0): """ XFetch Probabilistic Early Expiration algorithm. Prevents cache stampedes by recomputing key asynchronously BEFORE expiration. :param key: Cache key identifier :param beta: Aggressiveness factor (> 0). Higher beta = earlier proactive compute. """ value, delta, ttl_timestamp = redis_client.get_with_metadata(key) now = time.time() # Probabilistic early compute check: # - delta: Time taken to compute the value from the database original source. # - random.random(): Uniform random float between 0.0 and 1.0. # - math.log(): Natural logarithm. if value is None or (now - (delta * beta * math.log(random.random()))) >= ttl_timestamp: # Asynchronously lock or recompute value from database new_value, compute_time = db_client.compute_expensive_query(key) new_ttl = now + 3600 # 1 hour TTL extension # Write updated value along with its compute duration back to cache redis_client.set_with_metadata(key, new_value, delta=compute_time, ttl_timestamp=new_ttl) return new_value return value
How XFetch Protects the Pipeline:
As the cache key approaches expiration, the term -(delta * beta * log(random())) yields a probabilistic truth value. When traffic spikes, the probability that exactly one worker node triggers an early recompute before key expiration approaches 100%, while preventing the remaining 499,999 requests from hitting the database simultaneously!
Solution 2: Distributed Singleflight Request Coalescing
In singleflight request coalescing, concurrent duplicate requests on a node are merged into a single execution thread using shared synchronization promises.
       Request #1 (Key: "User_10") ───┐
       Request #2 (Key: "User_10") ───┼───► [ Singleflight Engine ] ───► Query DB ONCE
       Request #3 (Key: "User_10") ───┘             │
                                                    ▼
                                    Broadcast Result to All 3 Requesters!
7. The Unified Architecture: Building a Sub-Millisecond 1M QPS Ingress Engine
To synthesize these non-blocking event loop, lock-free ring buffer, zero-copy, and anti-stampede techniques into a practical blueprint, let’s look at the production architecture for a 1,000,000 QPS backend server:

Step-by-Step Architecture Pipeline
                                  1,000,000 QPS Ingress Requests
                                                │
                                                ▼
  +------------------------------------------------------------------------------------------+
  | KERNEL LAYER: Linux io_uring Ring Buffer & eBPF Zero-Copy Packet Filter                  |
  +------------------------------------------------------------------------------------------+
                                                │
                                                ▼ (Zero Context Switch DMA)
  +------------------------------------------------------------------------------------------+
  | EVENT LOOP LAYER: Thread-per-Core Non-Blocking Engine (Epoll / Tokio / Netty)           |
  | Core 0 Engine         │ Core 1 Engine         │ Core 2 Engine         │ Core 3 Engine     |
  +-----------------------+-----------------------+-----------------------+------------------+
             │                         │                       │                       │
             └─────────────────────────┴───────────┬───────────┴───────────────────────┘
                                                   │
                                                   ▼
  +------------------------------------------------------------------------------------------+
  | INTER-PROCESS COMMUNICATION: Lock-Free Array Ring Buffers (CAS / Padded 64B Cache Line)  |
  +------------------------------------------------------------------------------------------+
                                                   │
                                                   ▼
  +------------------------------------------------------------------------------------------+
  | APPLICATION LAYER: Singleflight Request Coalescing & XFetch Probabilistic Cache Engine   |
  +------------------------------------------------------------------------------------------+
                                                   │
                                                   ▼
  +------------------------------------------------------------------------------------------+
  | PERSISTENCE STORAGE LAYER: Write-Ahead Log (WAL) & In-Memory Append-Only Memory Fabrics |
  +------------------------------------------------------------------------------------------+
Sequence of Operations (Microsecond Level Trace):========================================================================================000 µs: Network Interface Card (NIC) receives packet via DMA into kernel memory.001 µs: eBPF program filters and validates headers directly in the kernel space data path.003 µs: io_uring places descriptor into shared Completion Queue (Zero Syscall!).005 µs: Thread-Per-Core Event Loop reads data frame from zero-copy memory ring.008 µs: Singleflight engine checks local cache; key missing -> triggers XFetch evaluation.012 µs: Lock-Free Ring Buffer passes work task across CPU cores with zero lock contention.045 µs: Task processes business logic and appends record to in-memory WAL buffer.060 µs: Response packet drafted in zero-copy socket buffer and pushed directly to wire!========================================================================================Total Execution End-to-End Latency: < 100 Microseconds (0.1 milliseconds)!
8. Tactical Implementation Playbook for Early Career Engineers
To transition from high-level theoretical concepts to building production-grade server architectures, early-career software engineers should follow this structured implementation path:
1.Audit Thread Allocation & Context Switching Costs:Scope constraint: Profiling production runtime overhead.
Start by measuring current thread contention and context-switching rates on your backend servers. On Linux systems, run vmstat 1 or inspect /proc/status to analyze non-voluntary context switches (nonvoluntary_ctxt_switches).
If context switches exceed 50,000/sec per core, your application is burning CPU cycles on thread scheduling instead of executing logic.
2.Migrate Blocking I/O to Non-Blocking Async Primitives:Prerequisite: Eliminating blocking APIs in Event Loop execution threads.
Audit codebases for hidden blocking calls inside event loops or web frameworks:
- Replace synchronous database clients (
JDBC, synchronous drivers) with non-blocking reactive drivers (R2DBC, async drivers). - Replace synchronous HTTP clients with non-blocking async HTTP engines.
- Move unavoidable blocking tasks (such as disk file I/O or heavy cryptography) to an isolated, bounded worker thread pool.
3.Replace Mutex Locks with Atomic and Lock-Free Structures:Target: Reducing inter-thread memory contention.
Identify high-contention thread synchronization points (such as global counters, shared metrics, or task queues):
- Replace
synchronizedblocks orstd::mutexwith atomic memory operations (AtomicLong,AtomicReference, or CAS loops). - For high-throughput worker-thread queues, adopt lock-free SPSC/MPMC Ring Buffers (e.g., LMAX Disruptor pattern or Lock-Free Channels).
- Pad critical atomic variables to 64-byte boundaries to eliminate false sharing across CPU cores.
4.Protect Upstream Dependencies with Singleflight & Circuit Breakers:Target: Preventing cache stampedes and cascading infrastructure failure.
Implement request coalescing (Singleflight pattern) on high-traffic read paths to ensure that duplicate concurrent requests merge into a single outbound execution call. Apply XFetch probabilistic early recomputation to critical cache keys to prevent cache stampedes before TTL expiration.
9. Conclusion: Developing System-Level Intuition
Building high-performance server architectures requires understanding how software abstractions interact with underlying hardware realities.
When a server infrastructure fails under heavy load, the solution is rarely to simply throw more hardware at the problem. True resilience comes from understanding the execution pipeline end-to-end:
- The Operating System Kernel: How thread context switching and system call overhead impact execution speed.
- The CPU Hardware Architecture: How cache lines, atomic CAS instructions, and memory buses handle concurrent access.
- The Network Stack: How non-blocking event loops, zero-copy buffers, and request coalescing prevent bottlenecks.
By mastering these low-level mechanics, you can design, build, and debug systems that stay fast, resilient, and stable—even under the most demanding production workloads.
Leave a Reply